What the adoption figures do and do not tell us
An April 23 Breaking Defense report quoted an unnamed Pentagon official saying users had built over 103,000 agents in fewer than five weeks, recorded more than 1.1 million sessions, and were averaging about 180,000 sessions per week by mid-April. Reported uses included drafting after-action reports and staff estimates, reviewing strategy and financial material, and describing imagery. The report also described IL5 authorization and officials' statements that evaluation teams and operational boundaries were in place. Firsthand reporting and official responses
Those are attributed platform-use figures. An agent count can include a widely shared tool, a narrow personal assistant, and an experiment used once. A session is a use event, not necessarily a completed task, a distinct user, or a correct result. The figures support an assessment of rapid adoption; they do not establish a historic deployment-speed record or an enterprise-wide error rate.
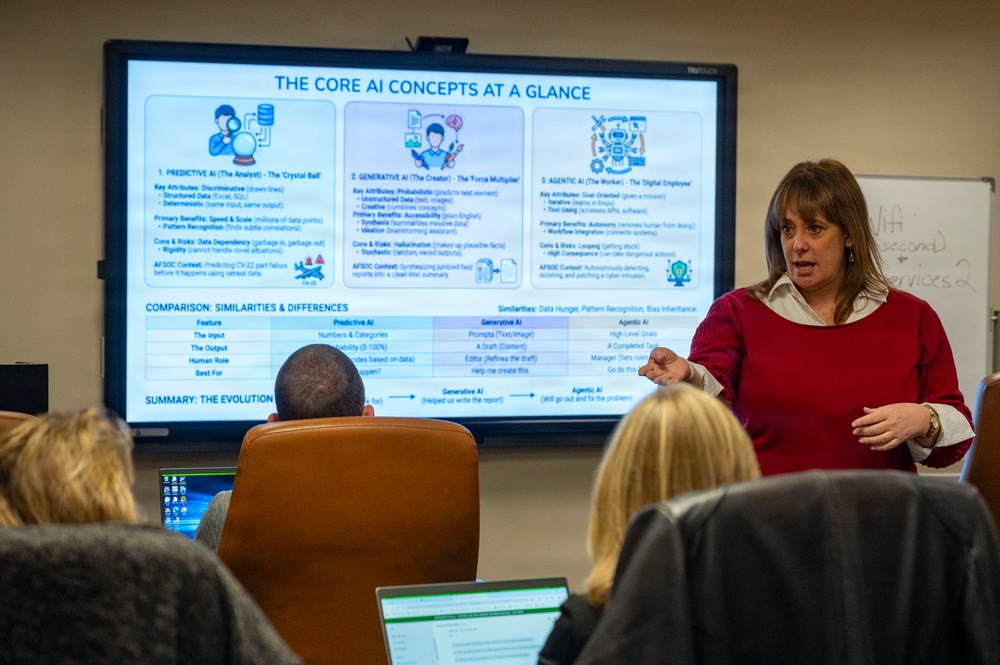
The label agent also covers different capabilities. A configured drafting assistant can present a result for review, while another workflow may invoke tools or change a record. The relevant risk depends on what it can access and do, who uses it, and how its output enters the next decision.
Keep three layers of assurance connected
Platform assurance addresses the hosting environment, access controls, authorized data handling, system boundaries, and supporting services. Workflow assurance addresses the instructions, selected model, retrieval sources, tools, permissions, and expected behavior of a particular configuration. Operational assurance examines whether the workflow continues to perform acceptably for the people and tasks using it.
These layers overlap. A secure host cannot make every generated statement accurate, while careful output review cannot compensate for excessive tool permissions or an exposed data source. Risk can originate in the underlying model, its configuration, the information it receives, or the way a user relies on the result.
Traditional authorization remains relevant. NIST's RMF includes continuous monitoring and ongoing authorization; it does not require the fiction that every application's behavior is fixed forever. The work is to extend the evidence and change-management process to the characteristics of AI-enabled workflows. NIST RMF
For example, an assistant summarizing obligation data might repeat a stale figure, omit an exception, or infer a conclusion that the records do not support. An imagery-description tool might perform poorly on an unfamiliar view. These are illustrative failure modes, not measured GenAI.mil incidents. Their consequences should determine the review needed before an output becomes an official product.
The statutory calendar has several milestones
FY2026 NDAA Section 1533, rather than the January AI strategy, sets the relevant assessment-team deadlines. It requires the cross-functional team by June 1, 2026, functional leads by January 1, 2027, the standardized framework and governance structure by June 1, 2027, and assessments of defined major AI systems by January 1, 2028. Its scope includes performance, documentation, testing, ethical principles, security, and use-case review. Those requirements do not establish whether implementation milestones have already been met. Enacted Section 1533
Section 1535 separately directs an AI Futures Steering Committee to address advanced AI, including risk-informed adoption and operational effects. CRS describes that committee's distinct role and its required reporting. CRS on agentic AI and the statutory framework
Program teams should determine how their use cases fit applicable policy and definitions. It would be premature to assume that user-created agents are categorically excluded from the assessment effort, or that all configurations must receive identical reviews. A meaningful implementation can apply common controls while scaling scrutiny to the consequence and reach of a workflow.
Build a usable inventory, then evaluate by risk
The inventory should be light enough that users keep it current and complete enough that owners can act on it. For each shared or consequential workflow, record:
- Its purpose, owner, intended users, and permitted operating context.
- The model and configuration version, connected data sources, and available tools.
- Whether it only drafts information or can make changes and take external actions.
- Required human reviews, known limitations, and where to report a problem.
- The evaluation evidence and the changes that trigger another review.
A reusable personal drafting aid and an agent that updates authoritative records should not have the same approval path simply because both were built with a low-code interface. The latter requires closer attention to authority, transaction limits, validation, and recovery.
NIST's generative-AI profile provides a foundation for assessing issues such as confabulation, information integrity, and human reliance. Its recommended lifecycle approach helps connect those risks to testing and ongoing monitoring. NIST generative-AI profile
Sample behavior without pretending sampling proves everything
An audit analogy is useful: test representative outputs against evidence, investigate anomalies, and follow corrective actions to closure. That analogy supplements engineering and authorization; it does not imply financial audits inspect every transaction or continuously verify every result.
A practical evaluation loop should:
- Build representative cases with reliable reference answers or clearly defined acceptance criteria.
- Include difficult inputs, missing information, misleading retrieved text, and tasks the agent should decline or escalate.
- Review outputs and tool actions, with more attention to high-impact workflows and newly changed configurations.
- Separate model-quality failures from source-data, permission, and user-interface failures so remediation reaches the right owner.
- Retest after a change and preserve enough version history to explain which users and results may be affected.
Monitoring must also respect the data's handling requirements. Record access and retention should be deliberately designed, and logs should not become an uncontrolled second copy of sensitive material.
The objective is a workforce that can build useful tools without losing visibility into their behavior. Adoption is strongest when users know which tasks a workflow has been evaluated for, when to check its work, and how to stop relying on it when conditions change.
Shared agents change the economics of review
An agent that begins as one person's drafting aid can acquire a much wider audience without changing its underlying instructions. The original owner may understand its limits; later users may see only a convenient name and a successful demonstration. Sharing therefore changes the assurance question even when the model version stays the same.
For a hypothetical example, a staff member builds an assistant to summarize a defined collection of administrative guidance. A second office adopts it for a related process and adds its own reference documents. The resulting tool may look like the original while answering from a different body of information. The first office's evaluation cannot establish the reliability of the second office's new use without examining that difference.
This is a reason to make reuse traceable, not to require a full enterprise review of every personal experiment. A useful publishing boundary would identify the supported purpose, accountable owner, source collection, and conditions on sharing. Moving beyond those conditions should trigger an assessment proportionate to the change. The goal is to preserve what made the original tool useful without allowing its reputation to substitute for evidence in a new setting.
Review effort can then be concentrated where reach and consequence justify it. A frequently used shared assistant merits different attention from an unused prototype. A narrowly scoped tool that changes an authoritative record may deserve more scrutiny than a popular brainstorming aid. Neither popularity nor technical complexity alone is a reliable risk ranking.
Separate improving the tool from repairing its effects
When an evaluation finds a problem, correcting the agent is only one part of the response. The owner also needs to determine whether previously issued work products require attention. That depends on the failure, the available history, and how the outputs were used; it should not be assumed that every prior result is wrong or that a corrected prompt fixes prior decisions.
A practical incident record should identify the affected configuration, the issue's known scope, the supported correction, and who will decide whether downstream users need notice. Records should remain proportionate to the data-handling constraints already discussed. An assurance process should not create a new repository of sensitive content simply because retaining everything would make an investigation easier.
This distinction gives leadership a better measure than raw agent growth: can the organization identify a consequential failure, assign it, correct its cause, and address its known effects? A sampled review of that process can reveal whether assurance is keeping pace with adoption without pretending to inspect every generated answer.
Sources and further reading
- Breaking Defense: reported adoption metrics and Pentagon safeguards
- FY2026 NDAA Section 1533, official statutory text
- CRS: agentic AI and Section 1535
- NIST: risk management and continuous monitoring
- NIST: generative-AI risk profile
Spartan X's AI consulting and cybersecurity practices bring workflow evaluation, permission design, and accountable deployment into the same effort. That combination supports rapid adoption with evidence that leaders and users can apply to real decisions.